A fun realization from working with Blackwell (SM100): we are basically back to solving NUMA problems, but inside a single GPU package.
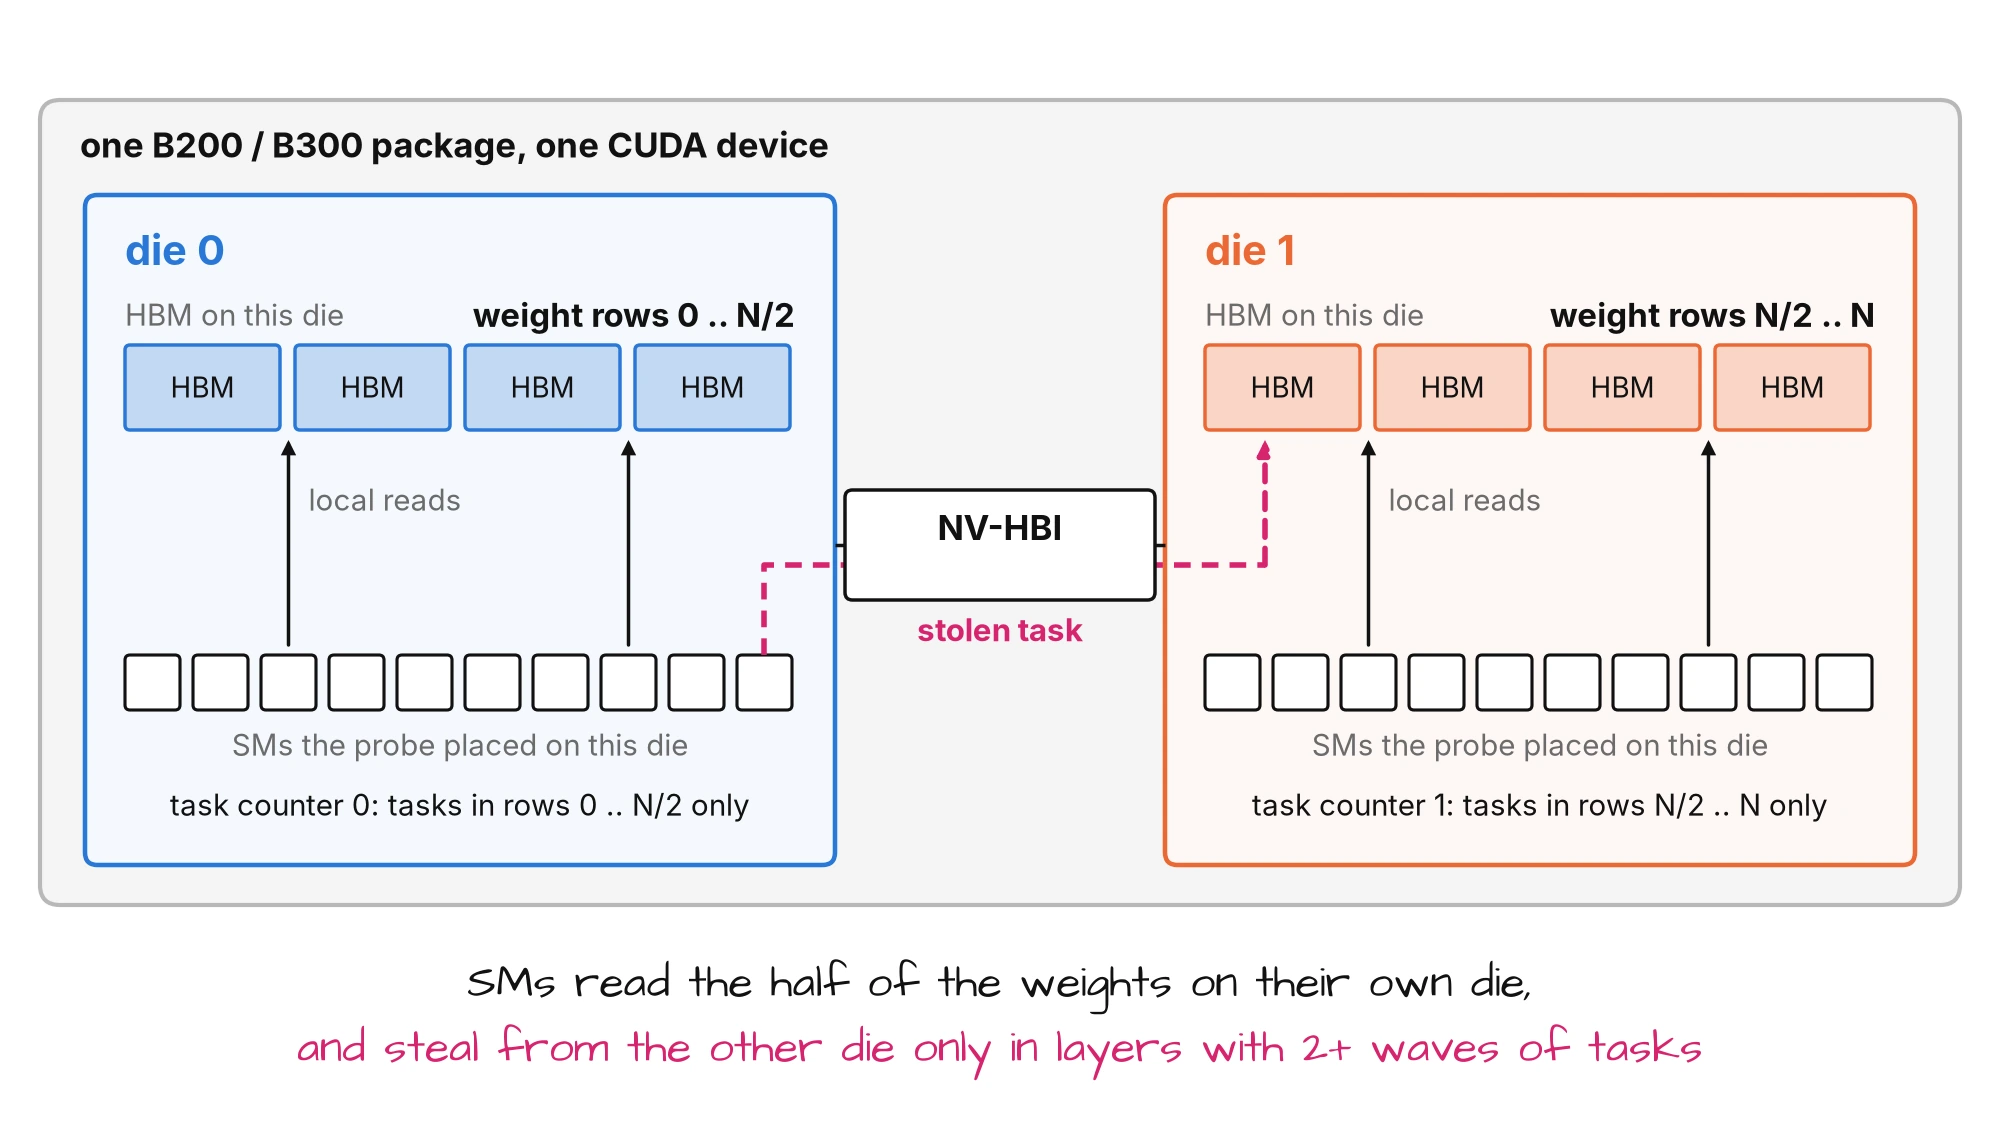
To software, a B200 or B300 looks like one big GPU. CUDA shows one device with a flat address space and a unified L2, and you launch kernels across all the SMs just like you did on Hopper. Physically, though, it is two separate silicon dies joined by NV-HBI. That link has huge bandwidth, but HBM attached to your own die is still noticeably closer than HBM attached to the other one. If you ignore this, memory-heavy kernels like MoE layers will spend half their time pulling weights across the link, which burns latency and power for no good reason.
DeepSeek recently handled this in DeepGEMM for their MegaMoE kernel (deepseek-ai/DeepGEMM#462). All the code below comes from that implementation.
Two locality domains#
Each die is basically a locality domain with its own SMs and its own HBM stacks. The funny thing is that CUDA has no API that tells you which SM sits on which die, so DeepGEMM just measures it empirically at startup. It puts one buffer on each die and has every SM chase a chain of pointers through both, timing the hops with clock64:
template <uint32_t kNumHops, uint32_t kNumChunksPerSM, uint32_t kNumChunkBytes>
__global__ __launch_bounds__(32, 1)
void locality_domain_probe_chase(const uint32_t* buf, uint16_t* out) {
    if (threadIdx.x != 0)
        return;
    const auto sm_idx = ptx::get_sm_idx();
    for (uint32_t chunk_idx = 0; chunk_idx < kNumChunksPerSM; ++ chunk_idx) {
        const auto chunk = buf + static_cast<uint64_t>(sm_idx * kNumChunksPerSM + chunk_idx) * (kNumChunkBytes / 4);
        uint32_t idx = ptx::ld_global_cg(chunk);
        const auto start = clock64();
        #pragma unroll
        for (uint32_t i = 0; i < kNumHops; ++ i)
            idx = ptx::ld_global_cg(chunk + idx);
        const auto cycles = clock64() - start;
        out[sm_idx * kNumChunksPerSM + chunk_idx] = idx == 0xffffffffu ? 0u : static_cast<uint16_t>(cycles / kNumHops);
    }
}
The probe setup here is pretty clever. It launches one 32-thread block per SM, and each block reserves the full capacity of shared memory so no SM can run two of them at once. Only thread 0 does the chase. Each 4 KB chunk is 32 cache lines, and each line points 7 lines ahead, so every single load is forced to wait on the one right before it. The loads use ld.global.cg to bypass L1, and L2 is flushed beforehand, meaning the measured cycles reflect raw HBM round-trip latency.
Each SM is assigned to whichever die it reads faster, taking the median over 8 chunks. The measurement is only accepted if the far die is at least 1.25x slower across the board and both SMs in every TPC agree. The two SMs in a TPC are physically paired together, so if they disagree, you know the measurement is noisy and can’t be trusted. DeepGEMM retries up to 5 times and otherwise falls back to an even split. And because the scheduler expects an exact 50-50 balance, any slight asymmetry from harvested SMs gets smoothed out by reassigning a few TPCs to the smaller side.
Slicing the weights across dies#
Once you know where each SM lives, the next problem is memory placement. Instead of storing MoE weights as one big flat array, MegaMoE splits each tensor along N. So (*B, N, K) becomes (2, *B, N/2, K), with slice d stored in die d’s HBM:
def localize(t: torch.Tensor, dim: int = -2) -> torch.Tensor:
    num_domains, dim = get_num_locality_domains(), dim % t.dim()
    assert t.size(dim) % num_domains == 0
    localized = empty_per_domain((*t.shape[:dim], t.size(dim) // num_domains, *t.shape[dim + 1:]), t.dtype)
    localized.copy_(t.unflatten(dim, (num_domains, -1)).movedim(dim, 0))
    return localized
Behind the scenes, empty_per_domain reserves one virtual address range and maps each half onto physical memory on its own die using the CUDA virtual memory APIs (cuMemAddressReserve, cuMemMap). CUDA cannot allocate on a specific die directly yet—that should arrive in CUDA 13.4. Until then, DeepGEMM gets die-local memory through MLOPart, an MPS mode that exposes each die as a separate CUDA device. DeepGEMM spins up a private MPS server in a helper process, does the allocation there, and passes each chunk back to the main process as a shareable file descriptor.
Affinity scheduling and work stealing#
Having localized data only helps if your thread blocks run on the right SMs. MegaMoE uses a persistent scheduler where each die gets its own task counter. A task pulled from die d’s counter naturally maps to die d’s half of N, so by default an SM only reads weights from its own local HBM. When its own queue runs dry, an SM can steal from the other die, but only if the layer has at least two waves of work. For smaller layers, stealing is skipped entirely:
template <uint32_t kNumClusters>
static CUTLASS_DEVICE bool get_next_task_idx(const uint32_t* task_count_ptr, const uint32_t& locality_domain_idx, const uint32_t& num_m_blocks,
                                             uint32_t& m_block_idx, uint32_t& n_cluster_idx) {
    constexpr uint32_t kNumLocalClusters = kNumClusters / kNumLocalityDomains;
    // One lane does an atomic add on this die's counter and broadcasts the result
    const uint32_t task_idx = get_next_local_task_idx(task_count_ptr, locality_domain_idx);
    if (task_idx >= num_m_blocks * kNumLocalClusters)
        return false;
    m_block_idx = task_idx / kNumLocalClusters;
    // Clusters [d * kNumLocalClusters, (d + 1) * kNumLocalClusters) cover die d's half of N
    n_cluster_idx = locality_domain_idx * kNumLocalClusters + task_idx % kNumLocalClusters;
    return true;
}

template <uint32_t kNumClusters>
CUTLASS_DEVICE bool get_next_task_idx(const uint32_t* task_count_ptr, const uint32_t& num_m_blocks,
                                      uint32_t& m_block_idx, uint32_t& n_cluster_idx) const {
    // 1. This SM's own die first
    if (get_next_task_idx<kNumClusters>(task_count_ptr, sm_locality_domain_idx, num_m_blocks, m_block_idx, n_cluster_idx))
        return true;
    // 2. Steal from the other die only with 2+ waves of work (one wave = kNumSMs / 2 two-SM clusters)
    return kNumLocalityDomains > 1 and num_m_blocks * kNumClusters >= kNumMinStealWaves * (kNumSMs / 2) and
           get_next_task_idx<kNumClusters>(task_count_ptr, sm_locality_domain_idx ^ 1, num_m_blocks, m_block_idx, n_cluster_idx);
}
This threshold makes total sense. Stealing work across dies means accepting higher memory latency and congesting the link. If you only have a few leftover tiles, it is faster to just let the local die finish them rather than paying the cross-die transit cost. So the scheduler only lets SMs steal when there are at least two full waves of work left, which is enough to amortize the penalty.
Hardware addressing with TMA#
A really nice detail is how this interfaces with the Tensor Memory Accelerator (TMA). The weight tensor map is simply set up as a 4D descriptor where one dimension is the die index: [K, N/2, die, expert]. Instead of doing messy pointer math in PTX, each CTA just picks the half with a coordinate:
// Each CTA of the 2-SM cluster loads its own BLOCK_N slice
const auto n_block_idx = task_info.n_cluster_idx * 2 + (is_leader_cta ? 0u : 1u);
// half_idx: which die's slice holds this N block
const uint32_t half_n = shape_n / 2, n_idx = n_block_idx * BLOCK_N, half_idx = n_idx >= half_n;
const uint32_t half_n_idx = n_idx - half_idx * half_n, expert_idx = task_info.is_shared() ? 0 : task_info.local_expert_idx;

// TMA coordinates: [k, n within the half, die, expert]
tma::copy_nd<BLOCK_K, LOAD_BLOCK_N, kSwizzleBMode, weight_dtype_t, 4>(
    tensor_map_b_ptr, &shared_storage.full_barriers[stage_idx], shared_storage.smem_b[stage_idx],
    2,  // 2-CTA load: completion is signaled to the leader CTA's barrier
    k_idx, half_n_idx, half_idx, expert_idx);
The stride along the die dimension steps directly across the physical split in memory, so half_idx decides which die serves the load. Normally that coordinate matches the SM’s physical die, so traffic stays purely local. Only stolen tasks, or SMs on reassigned TPCs, ever read across NV-HBI. And the inner loop doesn’t need any branch instructions or address recalculation.
DeepSeek’s release notes mention this saves about 100 W of package power and gives 5-10% higher GPU clocks under heavy load.
As AI chips continue to scale by stitching multiple dies together, hardware is becoming less uniform rather than more uniform. Treating the GPU as a collection of localized domains takes a bit more engineering up front, but it is one of those clean systems optimizations that pays for itself.